 Pernithia Galnith
Ways to Evaluate Technical Claims in Esports Articles matters because technical numbers shape how readers judge players, teams, and balance changes. Journalists and fans face a flood of metrics, KDA, GD@15, HLTV-style ratings, and must separate verifiable facts from interpretation. This guide gives clear, practical steps reporters and followers can use immediately: how to judge sources, inspect methodology, run quick reproducible checks, and spot common traps. It assumes the reader wants fast, reliable verification tactics they can apply to match reports, patch analyses, and performance pieces.
Key Takeaways
- Technical claims in esports articles significantly influence perceptions of players and teams, so accuracy is essential for trust and informed decisions.
- Prioritize verifying sources by confirming statistics come from official tournament pages, developer APIs, or authenticated data, not anonymous social posts.
- Always assess the methodology: clear definitions of metrics, adequate sample sizes, and transparency about statistical tests help ensure reliable conclusions.
- Apply quick checks by validating sources, sample details, and data snapshots such as VOD overlays to confirm reported statistics within minutes.
- Distinguish descriptive observations from causal claims and prefer articles that transparently update or correct mistakes to maintain credibility.
- Insisting on verifiable data, explicit metric explanations, and reproducible verification methods curbs misinformation and strengthens esports journalism.
Why Technical Claims Matter In Esports Reporting
Fact first: technical claims change reputations and decisions. A single reported win rate can shift fan perception, influence team scouting, and affect betting lines within hours.
Why this matters now: competitive ecosystems move fast. A 3% change in a champion’s pick rate or a 1.2 point swing in an HLTV-like rating can prompt roster moves or meta shifts. That makes accuracy a public good.
Concrete example: when an analyst claims a player’s KDA rose 40% after a patch, readers assume improved skill or meta fit. If that claim rests on three low-quality matches, the conclusion is misleading. Reporters and readers who check sample sizes and time windows avoid false narratives.
Practical consequence: outlets that separate raw data from interpretation build trust. For deeper context on esports technology and how data flows from games to stories, consult a concise tech guide.
Spotting Credible Sources, Data, And Expert Attribution
Answer first: prioritize primary, named sources. Official tournament pages, developer patch notes, and authenticated API outputs outrank social posts.
How to apply it: check whether a statistic cites an official feed (tournament operator or developer) or a community screenshot. If the article names an expert, confirm their role: is the person a team coach, a data scientist, or an anonymous Twitter account?
Red flags and real numbers: a claim like “Team X’s win rate dropped 18%” should include the sample window (e.g., 20 matches between June 1–30). Articles lacking dates or sample sizes are unreliable. A 5-match sample that shows an 18% swing is noise: 200 matches carries weight.
Sources to prefer: league registration pages, match VOD overlays, and developer API docs. For related context about how technology underpins reporting pipelines, link reporting can point readers toward a useful overview like the site’s piece on the impact of technology in esports.
Vulnerability note: many journalists once trusted a popular community spreadsheet that misattributed player IDs. The lesson: confirm identity against official rosters, not crowd spreadsheets.
Assessing Methodology, Metrics, And Statistical Rigor
Key answer: demand clear metric definitions and sample descriptions. A metric is only useful if its calculation and context are explicit.
Metric checklist: the piece should define KDA (what counts as an assist), KAST% windows, GD@15 calculation, HLTV-like rating formulas, and whether win rate is map-based or match-based. If a piece reports a “statistically significant” trend, it should state the test used and the p-value or confidence interval.
Sample-size rule of thumb: for individual player metrics, 30+ relevant rounds or 10+ matches start to reduce wild variance: for team meta claims, 100+ matches across the same patch give more reliable signals. Cite the window: “100 ranked matches from Patch 5.2 (May 1–20)” helps readers reproduce the claim.
Distinguish description from causation: good reporting says “after Patch 5.2, pick rate rose” (description) rather than “Patch 5.2 caused the rise” (causation) unless the article shows controlled comparisons. When authors attempt causal claims, they should reference established frameworks or prior studies: a useful companion discusses how teams use data in practice in the article on performance data.
Practical warning: small-sample analyses commonly overfit. One reporter who published a striking KDA-trend later retracted it after expanding the sample from 8 to 65 matches, the trend vanished. That retraction was visible and improved credibility: lack of correction is a red flag.
Quick Reproducible Checks And Practical Verification Steps
Direct answer: run three fast checks, source, sample, and snapshot. Each takes under five minutes for a single claim.
Step 1, Source check: open the cited tournament page, API feed, or patch notes. Match IDs and dates should agree. If the claim references a roster change, validate it against the official transaction wire or league roster list. For team-tech context, consult the piece on why teams are investing in infrastructure: roster and stat pipelines often link to those investments.
Step 2, Sample check: ask these three quick questions, how many matches, what dates, and which game mode? If the article omits any answer, request it. Recompute the metric across the same window if the data is public: most leagues publish match sheets or VODs.
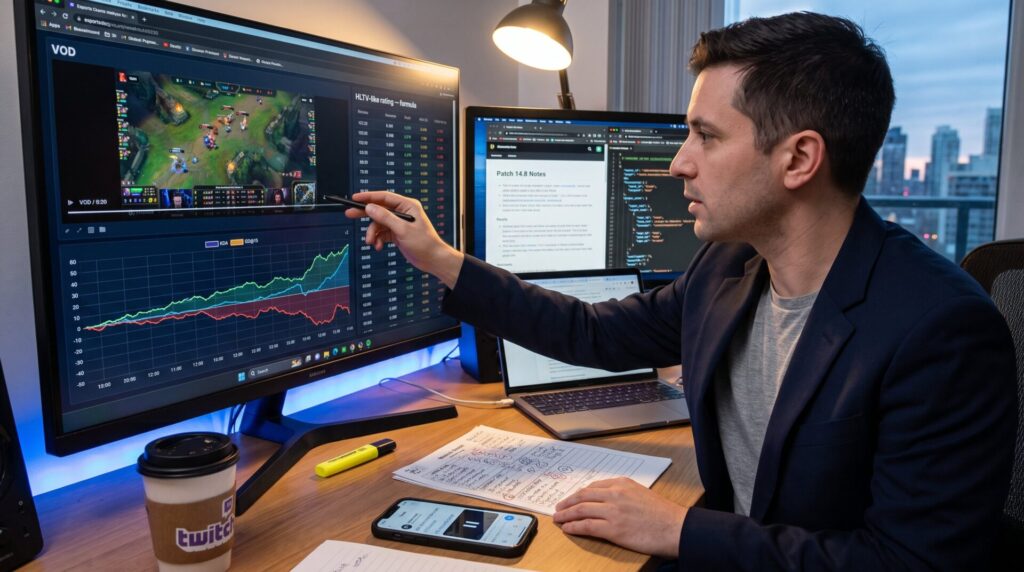
Step 3, Snapshot verification: watch the VOD or overlay for a single match to confirm a broadcast stat (e.g., a claimed 25% first-blood rate). A mismatch often signals a transcription error.
Extra practical tips: use archive snapshots when sources vanish, and save the exact query string or API call. When a claim relies on complex aggregation, ask for the author’s code or spreadsheet. Many reputable outlets publish methods on a companion page: a helpful practical reference is the site’s industry overview which lists public data releases and common datasets.
Ethical note: if a reader finds an error, contact the author with specifics (dates, match IDs, screenshots). Outlets that correct transparently strengthen trust.
Conclusion
Insight: trust grows when claims link to primary data, explain metrics, and include reproducible checks. Readers and journalists who insist on source names, clear samples, and easy verification stop misinformation early.
Next step: apply the three quick checks on the next match report read. For technical background on tools and APIs that feed coverage, the site’s articles on game APIs and hardware needs offer practical follow-ups.